About
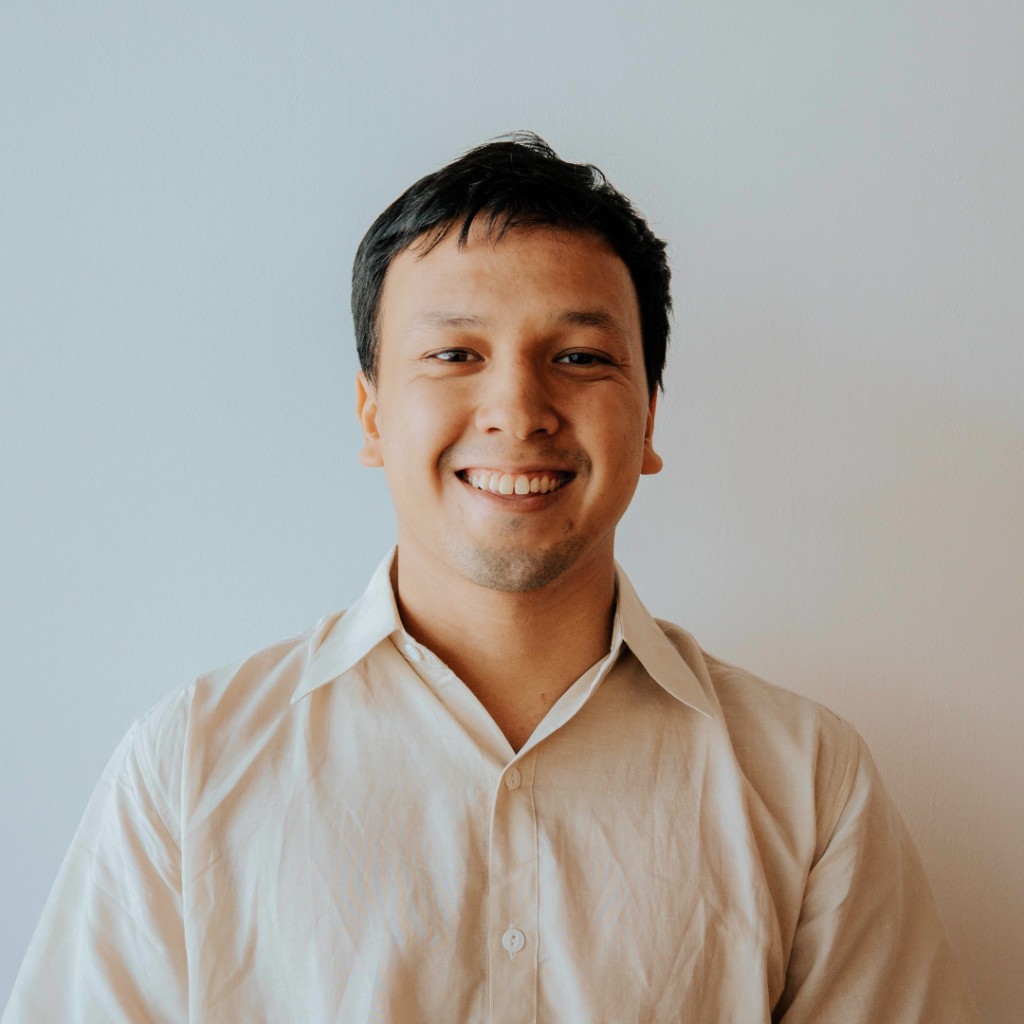
Aiman Farhan
Lead Full Stack Web & Mobile Engineer. I map painful workflows, then only build what clearly saves staff time or run cost.
I work with operators and teams who are drowning in dual systems, retyping, and vendor tools that never quite talk to each other. The pattern is the same whether it is access control, bookings, CRM, billing, or the spreadsheet that still runs the shift: hours leak, errors stack up, and the bill for “keeping it alive” keeps climbing.
My recent delivery focus has been multi-site ops platforms: syncing systems of record, booking-linked entitlements, internal enablement for floor teams, and taking over live stacks so finance and hosts are not stuck in missing-invoice mode. The niche is not “build an app.” It is automations and cutovers that pay back in staff hours and run cost.
I ship as a lead contributor end-to-end: product surface, background jobs, repair paths, and the wiki so the team can run it without me. I also architect for reliability: upgrades, backups, failover, and hardening so systems stay safe after launch, not just on demo day.
How I work
Transparency on scope, time, and progress. No black-box delivery.
Milestone first
We commit to a major milestone before build starts. Scope is written. Anything outside it is a new conversation, not a silent expand.
Base / worst / best
I estimate timelines three ways: base case, worst case, and best case. You see the range up front so “when will it be done?” is not a surprise later.
Daily + weekly reports
While work is in flight you get daily and weekly reports from me on what shipped, what’s blocked, and what’s next. Progress is visible without chasing.
Systems that stay reliable
Ongoing audits and upgrades. Not only features, but the rails under them.
01
System updates & upgrades
Keep the stack current and secure. Dependency upgrades without leaving production fragile.
02
Frontend modernisation
Adopt clearer UI stacks so the team ships faster, without a rewrite for its own sake.
03
Database snapshots & recovery
Reliable restore points for the data the business depends on.
04
Server & DB failover
Recovery paths when hosts or databases fail, so an outage is a drill, not a scramble.
05
Edge & network protection
Harden public surfaces against common network attacks (including AWS Shield-style controls where they fit).
06
Ongoing maintenance
Ops and finance inquiries, bug-fixing, and small enhancements so the system stays trustworthy day to day.
Selected work
Anonymised. Named clients only with clearance.
Dual-system sync
Removed retyping between a primary ops system and a third-party vendor tool. Bulk sync, repair when IDs drift, and runbooks so floor teams recover without waiting on engineering.
Booking-linked access
Rolled out entitlement tied to real booking time across multi-site, multi-timezone centres. Grant, revoke, no-show cleanup, and ops visibility when access changes.
Platform takeover
Rebuilt and cut over a live booking and billing stack. Indicative maintenance dropped by about RM 7,500/mo, with invoice and org integrity restored for finance.
Self-serve deflection
Shipped customer-facing booking and pass flows so staff stop babysitting routine requests. About 81% self-serve on routine room activity; 30%+ of bookings via mobile.
Tools I reach for
- Ruby on Rails
- React / Inertia
- Expo / React Native
- Access & OIDC integrations
- Background jobs & sync repair
- Ops tooling & internal wikis
- CRM lead capture
- Billing continuity
- Platform takeover & cutover
- Upgrades, backups & failover
- Production hardening
Want the same discipline on your workflow?
Fifteen minutes to see if there is a fit. No pitch deck required.
Book a 15-minute intro